

锦囊AI
雷光 单 · Utilities
Independent analytics for this App Store listing. AppTracker is not affiliated with 雷光 单.
Chart standing · US
What changed · US
Listing changes AppTracker has observed for this app in this storefront — new versions, price moves, rating shifts, and store copy.
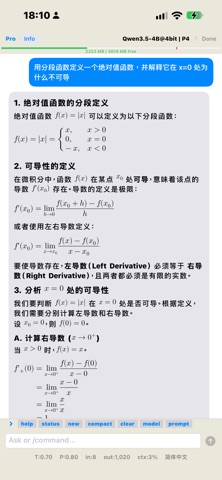
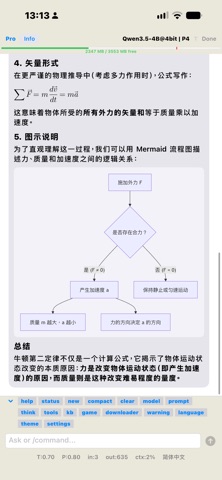
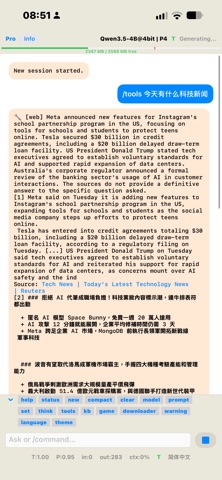
v1.5 — a new engine and a refreshed reading experience ENGINE UPGRADE • Upgraded to the latest MLX inference engine — fixes around long-conversation caching, multi-turn memory drift and tool-call arguments • Models now load only when you start chatting, so nothing is held in memory at launch • A hard KV cache cap keeps long conversations and auto-compaction clear of the memory ceiling READING • Full LaTeX rendering — fractions, roots, matrices, cases and boxed answers now display correctly • Fixed formulas that failed to parse, and ones that vanished entirely when parsing failed (worst case now falls back to the raw text) • Markdown rendering: headings, lists, tables, quotes, bold/italic, links • Code blocks and inline code render separately; fenced code no longer mistaken for math • New "General Rendering" section to control LaTeX and Markdown rendering independently (turn Markdown off to copy raw text); charts and diagrams are enabled per prompt ANSWER LENGTH • Higher output limits: 0.6B / 1.7B from 768 → 1536, 4B models from 2048 → 3072 • When a reply hits the limit you now get a clear notice and a one-tap "Continue" WEB SEARCH (NEW, OFF BY DEFAULT) • New Web Search tool (used via /tools) • Two sources: Tavily (bring your own API key, free tier available) or Wikipedia • Results are collapsed by default, with tappable source links; the network is used only when you turn this on and run the tool COMMANDS & PANELS • All commands now open a panel you can tap through: /help /status /model /set /prompt /language /tools /kb /game /downloader • No arguments opens the panel; arguments still work as a command (e.g. /set top_p 0.8) • Settings come in three scopes: sampling (temperature / top P) follows the prompt (remembered per model × prompt); thinking, context, output, memory profile and KV reuse are remembered per model; rendering, auto-compact and network are global • "Reset to default" now resets only the current model FIXES • /language "Auto" now really follows your input language (the first reply used to come back in English) • Fixed the first exchange not appearing after starting a new session — it needed one more message before showing • Fixed "Reset to default" being capped at a 4096 context budget • Fixed thinking mode silently raising the output limit — what you set is now what you get • Qwen3-0.6B and 1.7B no longer think by default, so replies come back faster (turn thinking back on with /think) • Removed the unstable VibeThinker-3B model (7B / 9B models cover the same ground)
Screenshots

About
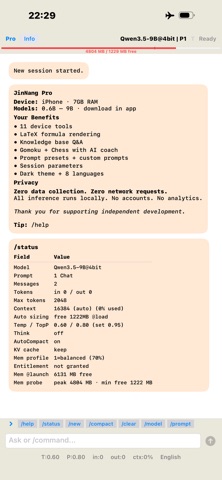
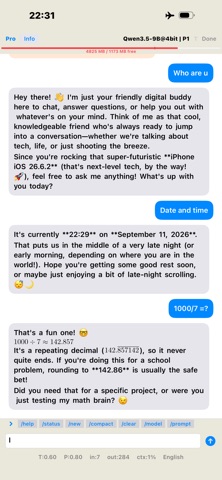
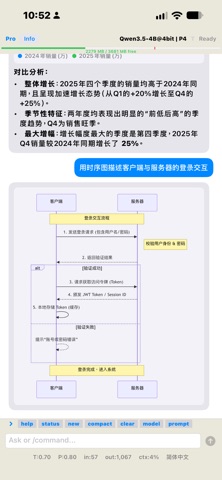
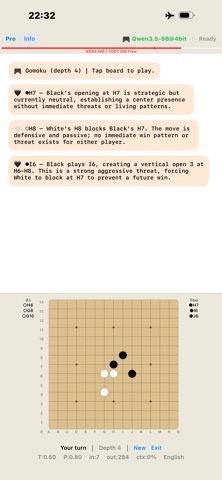
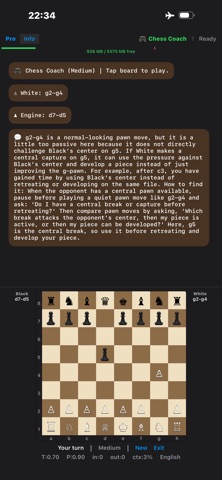
Clutcha AI— a smart assistant that runs entirely on your iPhone. Inference happens on-device, your conversations never leave the device, and there is no account and no data collection. • On-device inference: chat with no network connection (the network is only used to download models) • Upgraded to the latest MLX inference engine — steadier long conversations, more accurate multi-turn memory, more reliable tool calls • A lightweight model is built in and ready to use; download 4B / 7B / 9B models for more capability (7 in total) • 11 device tools: calculator, date & time, files, system, battery, translate, Safari, clipboard, reminders, location, contacts • Web search (new): optional and off by default, with Tavily and Wikipedia — source links can be opened to verify • Full LaTeX math and Markdown rendering: headings, lists, tables, quotes, code blocks. Turn rendering off to read the raw text • Longer answers, less often cut short: higher output limits, a clear notice when a reply hits the limit, and one-tap continuation • Settings and info commands open a panel: /help /status /model /set /prompt /language /tools /kb /game /downloader • Adjustable session settings: context window, temperature, thinking budget, memory ceiling — remembered per model, so switching models keeps each model's own settings • Sampling tuned to each model's official recommendations (Qwen3 / Qwen3.5 / Qwen2.5 / DeepSeek-R1) • Knowledge base Q&A, plus Gomoku and chess with AI review • Privacy first: no data collection, no tracking — your data stays on your device. Only if you turn on web search and run the tool is your query sent to the provider you choose • Requirements: tested on iPhone 15 Pro Max (8GB); 12GB and up leaves more headroom for large models • Pro unlocks: 4B / 7B / 9B models, Chess Coach, parameter tuning, custom prompts and web search
What's new · 1.5
v1.5 — a new engine and a refreshed reading experience ENGINE UPGRADE • Upgraded to the latest MLX inference engine — fixes around long-conversation caching, multi-turn memory drift and tool-call arguments • Models now load only when you start chatting, so nothing is held in memory at launch • A hard KV cache cap keeps long conversations and auto-compaction clear of the memory ceiling READING • Full LaTeX rendering — fractions, roots, matrices, cases and boxed answers now display correctly • Fixed formulas that failed to parse, and ones that vanished entirely when parsing failed (worst case now falls back to the raw text) • Markdown rendering: headings, lists, tables, quotes, bold/italic, links • Code blocks and inline code render separately; fenced code no longer mistaken for math • New "General Rendering" section to control LaTeX and Markdown rendering independently (turn Markdown off to copy raw text); charts and diagrams are enabled per prompt ANSWER LENGTH • Higher output limits: 0.6B / 1.7B from 768 → 1536, 4B models from 2048 → 3072 • When a reply hits the limit you now get a clear notice and a one-tap "Continue" WEB SEARCH (NEW, OFF BY DEFAULT) • New Web Search tool (used via /tools) • Two sources: Tavily (bring your own API key, free tier available) or Wikipedia • Results are collapsed by default, with tappable source links; the network is used only when you turn this on and run the tool COMMANDS & PANELS • All commands now open a panel you can tap through: /help /status /model /set /prompt /language /tools /kb /game /downloader • No arguments opens the panel; arguments still work as a command (e.g. /set top_p 0.8) • Settings come in three scopes: sampling (temperature / top P) follows the prompt (remembered per model × prompt); thinking, context, output, memory profile and KV reuse are remembered per model; rendering, auto-compact and network are global • "Reset to default" now resets only the current model FIXES • /language "Auto" now really follows your input language (the first reply used to come back in English) • Fixed the first exchange not appearing after starting a new session — it needed one more message before showing • Fixed "Reset to default" being capped at a 4096 context budget • Fixed thinking mode silently raising the output limit — what you set is now what you get • Qwen3-0.6B and 1.7B no longer think by default, so replies come back faster (turn thinking back on with /think) • Removed the unstable VibeThinker-3B model (7B / 9B models cover the same ground)
Details