

TensorFlow TFLite Debugger
Anh Nguyen · Developer Tools
Independent analytics for this App Store listing. AppTracker is not affiliated with Anh Nguyen.
Chart standing · US
What changed · US
Listing changes AppTracker has observed for this app in this storefront — new versions, price moves, rating shifts, and store copy.
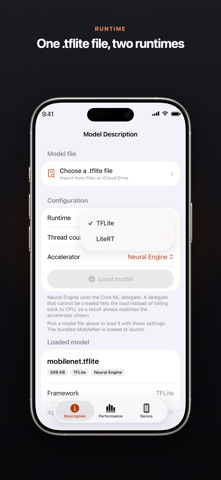
Now available in German, Japanese, Korean and Simplified Chinese. LiteRT v2 joins TensorFlow Lite as a second inference runtime. Pick the engine on the Model Description tab and benchmark the same .tflite file on either one. LiteRT runs on CPU and GPU; the Neural Engine path remains TFLite-only for now. All three tabs have been redesigned: the latency and throughput figures now lead, tensor details are easier to read, and memory and storage are shown as live bars. Your models and your results still never leave the device.
In-app purchases · US
No in-app purchases.
Screenshots


Keywords this app targets
Search terms AppTracker associates with this app — estimates, not search volume. ❝ = in the app's title; a highlighted number is its current position for that term.
Similar apps
Competitors and close alternatives, as estimated by AppTracker.
 VRAMFit: LLM Calculator
Sarvesh Anand Kandala
1 shared topic
 LLM Server
Linosec
1 shared topic
 LemoLM: Local LLM & AI Chat
PAUL ANTHONY HADFIELD
 Models Zoo
Daisuke Majima
 Neural Object Detector
BYFLARE TECHNOLOGIES (OPC) PRIVATE LIMITED
2 shared topics
 CoreAI Zoo
Daisuke Majima
 DeviceLab - Phone Benchmark
Shanghai Aisujiao Network Technology Co., Ltd.
 Pocket AI Lab
HAOTONG TECHNOLOGY (HK) CO., LIMITED
About
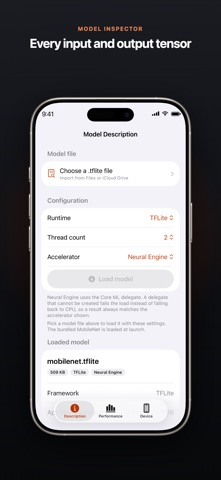
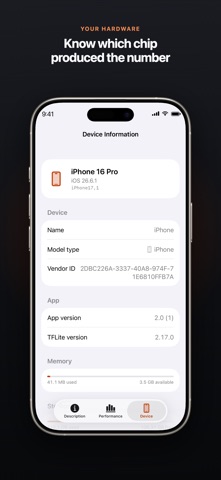
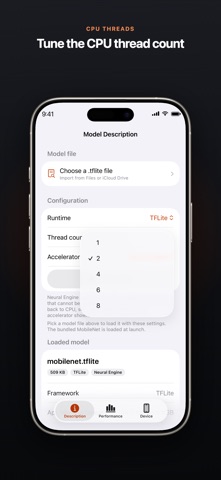
How fast does your .tflite model actually run on this iPhone? Pick CPU, GPU or Neural Engine. Get real latency and QPS. No Mac, no Xcode project, no Bazel build, no cloud, no account. Open a .tflite file from the Files app, pick an accelerator, run it. A real measurement on the exact device you care about, in about a minute — no Bazel workspace, no benchmark tool built from source. PICK THE ACCELERATOR - Neural Engine — attaches the Core ML delegate, so supported operators run on the Apple Neural Engine - GPU — attaches the GPU delegate, backed by Metal - CPU — the plain interpreter, with a thread count you choose: 1, 2, 4, 6 or 8 One configuration per run: run it, change the delegate or thread count, load it again, compare the numbers yourself. WHAT YOU GET - Latency: mean, min and max, in milliseconds - Queries per second - Total queries completed and total run duration - A query count you set per run, from 50 to 5,000 invocations Mean, min and max time the model inference call only — no pre-processing, no post-processing. Duration covers the whole loop. The screen stays awake during a run. WHAT YOU SEE ABOUT THE MODEL - Every input and output tensor: index, name, shape and data type (uInt8, int32, float16, float32 and the rest) - Model file size and framework - Live app memory usage against the memory available to the app, refreshed while the model runs - A device tab with model identifier, system version, disk space, and the exact TensorFlow Lite runtime version this build links against A MobileNet model ships in the app and loads on launch, so you see a real measurement before importing your own. READ THIS BEFORE YOU TRUST A NUMBER Inference runs on a zeroed dummy input. The app fills every input tensor with zeros and invokes the model, so what you measure is the compute cost of the graph on the accelerator you picked — latency and throughput, nothing else. It is not an accuracy test. It will not tell you whether your model gives the correct answer, and it does not show output tensor values. Ask it "how fast", not "how correct". What it does not do, stated up front: no side-by-side accelerator comparison in one run, no per-layer or per-operator profiling, no result export, no image or real-data input. It opens .tflite files only. PRIVACY Your model never leaves the device. Loading, inspection, inference and timing all happen locally on your iPhone or iPad. No account, no sign-in — your models and your results are never uploaded. TensorFlow Lite is now called LiteRT; the format and the .tflite extension are unchanged. TensorFlow, the TensorFlow logo and any related marks are trademarks of Google Inc. Not affiliated with or endorsed by Google.
What's new · 2.0
Now available in German, Japanese, Korean and Simplified Chinese. LiteRT v2 joins TensorFlow Lite as a second inference runtime. Pick the engine on the Model Description tab and benchmark the same .tflite file on either one. LiteRT runs on CPU and GPU; the Neural Engine path remains TFLite-only for now. All three tabs have been redesigned: the latency and throughput figures now lead, tensor details are easier to read, and memory and storage are shown as live bars. Your models and your results still never leave the device.
Details